
Last updated: November 1, 2026.
If we want to see a page in Google, Google first has to know the page exists. Then it has to be able to reach the page, read its content and decide it’s worth indexing.
In this process, concepts like robots.txt, sitemap.xml, redirects, HTTP status codes, canonical and noindex aren’t independent of each other. All of them affect how Googlebot moves through a site.
I think it makes more sense to explain the topic through one question rather than one definition after another:
We created a new URL. How will Google find this page, and what happens after that?
1. How does Google discover a URL?
There are several ways Google learns about a new URL. Two of the most important are links and sitemaps.
Say you published a new blog post. If you linked to it from the homepage, a category page or another post, Googlebot can follow that link and discover the new URL.
That’s why the internal linking we talked about in Chapter 18 doesn’t just move users to other pages. It also helps Google discover new and existing pages. Google uses crawlable <a href> links to find new pages.
The other important source is sitemap.xml.
2. What does sitemap.xml do?
A sitemap is the file where we tell Google which URLs on our site we consider important.
For example, these can be submitted to Google through a sitemap:
- Products
- Categories
- Blog posts
- News articles
- Videos
- Images
But there’s a misunderstanding I see often here:
Adding a URL to the sitemap doesn’t mean Google will definitely crawl or index it.
A sitemap isn’t a guarantee; it’s a strong discovery tool. Google also treats a sitemap submission as a signal; it doesn’t guarantee that the URLs will be crawled or indexed.
3. Which URLs should go in the sitemap?
I think we can approach this with simple logic:
We should put the main URLs we want to see in Google into the sitemap.
For example, the pages in a sitemap should generally be:
- Returning a 200 status code
- Open to indexing
- The canonical URL we prefer
- Meaningful to users
- Pages we want to appear in Google
Google itself recommends adding the URLs we want to see in search results to the sitemap. Also, Google ignores the <priority> and <changefreq> values; it can use the <lastmod> information when it’s used correctly.
So I don’t think stuffing every URL you create into the sitemap file is the right approach.
4. A real sitemap problem we ran into
While working with a large news site, we had a problem where new articles were showing up in Google late. The article would be published, but Google sometimes noticed the new URL late.
When we looked at the technical side, we saw the sitemap file was being cached for about 10 minutes to reduce server load. So an article went live at 10:00, but its URL appeared in the sitemap around 10:10.
For a typical corporate site, 10 minutes may not matter much. But on a news site, 10 minutes can be a long time.
After we cut the cache duration down to seconds, we saw new articles get into the sitemap much faster, and the delayed indexing problem largely went away.
I especially like this example because it shows how much a setting that looks small in technical SEO can matter depending on the business model.
The crawling needs of an e-commerce site, a corporate site and a news site are not the same.
5. Google found the URL, now it checks robots.txt
robots.txt is one of the most misunderstood SEO files.
Put simply, with robots.txt we tell search engine crawlers: “You can crawl these sections of my site; stay out of these.”
For example:
User-agent: *
Disallow: /admin/
Here we’re telling Googlebot not to crawl the URLs under /admin/.
robots.txt lives in the site’s root directory: site.com/robots.txt
Google’s automated crawlers check the robots.txt rules before crawling a site.
6. You can’t remove a page from Google with robots.txt
I think this is one of the most important things to learn about robots.txt.
robots.txt is crawl control. noindex is index control. They’re not the same thing.
When you block a URL with robots.txt, Google can’t crawl the page’s content. But if it has learned about the URL from other places, in some cases the URL itself can appear in search results without a description. Google states this clearly in its own robots.txt documentation.
So if you’re saying “This page must never appear in Google,” robots.txt isn’t always the right solution.
7. What is noindex?
If we don’t want a page to appear in Google results, one of the methods we can use is noindex.
For example, the page might have this tag:
<meta name="robots" content="noindex">When Googlebot crawls the page, it sees this tag and understands the page shouldn’t be shown in Google results.
But there’s a very important detail here:
Google has to be able to crawl the page first in order to see the noindex tag.
If you block the page with robots.txt and also use noindex, Google may never see the noindex tag because it can’t reach the page. Google’s own documentation specifically says the page must not be blocked by robots.txt for noindex to work.
In short:
- robots.txt: Crawling
- noindex: Index
Knowing this difference solves many technical SEO problems before they even happen.
8. When Google reaches a page, what does the server respond with?
When a crawler arrives at a URL, it gets an HTTP status code from the server.
You don’t need to memorize all of them when doing SEO, but you definitely need to know some:
| Status code | Meaning |
|---|---|
| 200 | The page loads successfully |
| 301 | Permanent redirect |
| 302 | Temporary redirect |
| 404 | Page not found |
| 410 | Content removed |
| 429 | Too many requests |
| 5xx | Server-side problem |
These codes don’t only concern developers. They also affect what Google does with the URL.
9. Does a 200 status code mean everything is fine?
A page returning 200 basically shows that the server responded to the request successfully.
But 200 doesn’t mean Google will definitely index it.
A page can be crawlable, return 200 and still not be indexed by Google. Because crawling and indexing are not the same process.
Google evaluates the pages it crawls afterward. Other factors come into play, such as whether the content is a duplicate, canonical signals or whether the page is eligible for indexing. Google’s crawl budget documentation also clearly states that not every crawled page will be indexed.
10. 301 Permanent Redirect
If a URL has moved permanently to another URL, we can use a 301.
For example, if our old product URL was site.com/old-coffee-machine and the new address is site.com/new-coffee-machine, and it really is the new address of the same product, the redirect can look like this:
old URL → 301 → new URL
This both takes the user to the right page and gives Google a strong signal that the old URL has moved permanently to the new address. Google counts permanent redirects among the strong signals for the canonical target, and it states that permanent redirects like 301 don’t cause a loss of PageRank.
11. 302 Temporary Redirect
A 302, on the other hand, says the change is temporary.
For example, if you’re sending users to another page because of a short campaign but plan to use the old URL again later, a 302 can make sense.
Google treats a 301 as a stronger signal that the target URL should be the canonical one, and a 302 as a weaker signal.
In practice, the real question should be:
Is the change permanent or temporary?
You need to choose the status code based on that.
12. Should we redirect every 404 page?
No.
For a long time, SEO work developed this reflex: “Let’s 301 everything we see returning a 404.” I think that’s wrong.
If a product was removed and a genuinely similar or new product replaced it, a redirect can make sense. But redirecting the page for an event you held in 2017 to the homepage just so it doesn’t return a 404 doesn’t make much sense for users either.
If a URL really no longer exists, returning a 404 is normal.
Google also treats 404 and other 4xx status codes as “the content no longer exists” and drops previously indexed URLs from the index over time.
A 404 isn’t always a technical SEO error.
A wrong 404 can be an error. A correct 404 is normal.
13. There’s no need for a big SEO battle between 404 and 410
410 Gone says the content was deliberately removed. 404 says it wasn’t found.
In its current documentation, Google treats most 4xx status codes, including 404 and 410, similarly for Google Search: the URL’s content is considered unavailable.
So instead of spending hours debating “Should we return a 404 or a 410?”, I think most projects should focus on more important technical problems.
14. Redirect Chain
Let’s imagine a setup like this: A → B → C → D
The user goes to URL A. A redirects to B. B to C. And C to D. In the end, the content loads at D.
We call this a redirect chain.
If possible, redirecting directly from A → D is cleaner.
Google recommends avoiding long redirect chains; unnecessary redirects can make things harder for both crawling and user experience.
We see these chains a lot, especially on sites that have been running for years. The old URL was changed once. It was changed again three years later. Then the site was redesigned. Each team added a new redirect. After a while, the URL’s history turns into a family tree.
15. Redirect Loop
The worse scenario is this: A → B but B → A
The user and Google keep going back and forth between two URLs. The page never loads.
We call this a redirect loop.
It can happen because of HTTPS migrations, www / non-www settings or wrong CDN / server rules.
Here, before SEO, the basic problem is:
The page isn’t accessible.
16. What does a canonical URL do?
Let’s say a page can be opened with more than one URL. For example:
site.com/shoes
site.com/shoes?color=black
site.com/shoes?utm_source=instagram
In some cases, the content can be completely or largely the same.
Google can look at these URLs and choose one of them as the canonical URL.
We can also tell Google which URL we prefer with this tag:
<link rel="canonical" href="https://site.com/shoes">But there’s an important word here too: Prefer.
A canonical isn’t a command; it’s a strong signal. If Google sees a reason to, it can choose a different canonical from the URL we specified.
17. Canonical and 301 are not the same thing
These two get mixed up often.
When you set up a 301, both the user and Google go to another URL. When you use a canonical, both pages can still be accessible to the user.
For example, a color-filtered category page (/shoes?color=black) may be useful for users. The user sees black shoes there. But you might want to tell Google that the main category URL is the standard version. In that case, a canonical can be used.
So a canonical doesn’t mean “Shut this page down.”
It means something more like “Within this group of similar URLs, this is the main URL I prefer.”
18. The sitemap and the canonical shouldn’t contradict each other
I think this is one of the very simple but common mistakes in technical SEO.
The page’s canonical tag says site.com/product-a. But the sitemap contains site.com/product-a?ref=xyz.
On one hand we’re telling Google, “This is the main URL.” On the other, we’re saying, “My important URL is that one.”
Google can treat URLs added to the sitemap as a canonical signal. So having technical signals support each other as much as possible creates a cleaner structure.
19. What is nofollow?
You may see rel="nofollow" on a link. Here we’re giving Google a signal about our relationship to the link.
But there’s still a lot of outdated information about nofollow on the internet.
Google now treats link attributes like nofollow, sponsored and ugc as hints for Search, rather than a strict “never follow” command.
So the logic “I absolutely want to block this page from being crawled, so I’ll put nofollow on the internal links” isn’t the right method.
Google recommends using appropriate methods such as robots.txt if you want to stop a URL on your own site from being crawled, and if you don’t want it indexed, leaving the page open to crawling and using noindex.
20. What is crawl budget?
Google doesn’t have infinite resources to crawl the entire internet without limits.
Every site has a crawl capacity and a crawl demand. We roughly call the combination of these crawl budget.
But I think the SEO industry has created a bit more fear here than necessary. A 50-page corporate site spending serious time on “How do we optimize our crawl budget?” is usually unnecessary.
Google’s current guide also defines crawl budget optimization as an advanced topic, especially for very large or very frequently updated sites. It gives large sites with millions of URLs, or sites with tens of thousands of URLs that change very quickly, as examples.
But if you’re managing a large site with millions of product URLs, filter combinations or a constant stream of new articles, the topic becomes important.
21. What can waste crawl budget?
Especially on large sites, these can cause problems:
- Unnecessary filter URLs
- Sorting parameters
- The same content opening at hundreds of URLs
- Infinite calendar URLs
- Long redirect chains
- Soft 404 pages
- Slow server responses
- Constant 5xx errors
- Large numbers of URLs with no crawl value
For example, on an e-commerce site, parameters like ?color=black, ?size=m, ?sort=price and ?brand=x can combine with each other to create hundreds of thousands of URLs.
In reality you have 10,000 products, but Google can discover millions of different URL combinations.
One of the important jobs of technical SEO is showing Google the truly important URLs more clearly.
22. Server performance can affect crawling
Google doesn’t want to crash your server while crawling your site.
If server response times get worse or a lot of 5xx / 429 errors happen, Google can reduce its crawl rate. When the server starts returning healthy 2xx responses again, crawl capacity can gradually increase.
So some crawling problems may not come from the SEO plugin but from:
- The server
- The CDN
- The database
- The cache system
- The application infrastructure
This is partly why technical SEO isn’t just “checking meta tags.” We look at the server and site speed in the next chapter.
23. How should pagination be handled?
Let’s say an e-commerce category has 2,000 products. We don’t load them all on one page; we split them into pages like this:
/coffee-machines?page=1
/coffee-machines?page=2
/coffee-machines?page=3
What matters here is that Google can reach the following pages.
In its current documentation, Google recommends giving each paginated page its own URL, linking the pages to each other with crawlable <a href> links and having each page use its own canonical URL. Canonicalizing all paginated pages to the first page isn’t the right approach.
Also, Google no longer uses these tags, which we often see in older SEO courses, to understand the pagination relationship:
<link rel="next" href="...">
<link rel="prev" href="...">
In SEO, you need to check old information as carefully as new information.
24. With infinite scroll, does Google see all the products?
Not always.
New products loading with JavaScript as the user scrolls down can be a nice experience. But Googlebot doesn’t scroll down the screen like a user and press the “Load More” button.
Google’s own documentation also says crawlers generally don’t click buttons that require user interaction. So in setups that use infinite scroll or “load more,” it’s important that the content is accessible through unique URLs and crawlable links.
We don’t want a setup where the user can see 500 products but Googlebot can discover only the first 20.
25. Mobile-First Indexing
Google now indexes and ranks based on the content of the mobile version of a site. We call this mobile-first indexing.
So building a great, comprehensive page on desktop and then removing half the content on the mobile version can cause problems.
Things to check in particular:
- Is the main content available on mobile?
- Are the headings the same?
- Are the images accessible?
- Are the internal links there on mobile too?
- Is the structured data consistent?
- Does robots.txt block mobile resources?
Responsive design usually makes this easier; Google also recommends the responsive approach because it’s easier to implement and maintain.
26. The difference between crawling and indexing
I think one of the most important distinctions in this chapter is here again.
Google can discover your page. Then it can crawl it. But it may still not index it.
For example, after crawling the page, Google may choose another URL as the canonical, or decide there’s no need to index the page.
So when we see a status like “Crawled – currently not indexed” in Search Console, it’s wrong to say “Google couldn’t find my page.”
Google found it and crawled it. The problem is at another stage of the process.
Trying to solve problems in technical SEO without making this distinction wastes a lot of time.
27. If Googlebot can’t reach a page, where do I look first?
I like to check roughly in this order:
- Does the URL actually load?
- What HTTP status code does it return?
- Is robots.txt blocking it?
- Is there a noindex?
- Which URL does the canonical point to?
- Is it in the sitemap?
- Does it get links from within the site?
- Can the link be discovered without JavaScript?
- Is there a redirect?
- Has a redirect chain formed?
- Can mobile Googlebot see the same content?
- Are there server errors?
- What does Search Console URL Inspection say?
Once you look at these, most of the problem already starts to narrow down.
28. I think the biggest mistake in technical SEO is looking at a single tag
For example, the developer says, “The canonical is correct.”
But the sitemap shows another URL. The internal links go to a third URL. The 301 redirects to a fourth URL. There’s a noindex somewhere. And robots.txt has blocked another area.
In this case, each setting may technically “work” on its own, but we’re sending Google contradictory signals.
I look at technical SEO a bit like this:
Drawing Google a path that’s as clear and consistent as possible.
Which URL is important? Which one should be crawled? Which one should be indexed? Which one no longer exists? Which one moved somewhere else? Which one is a different version of the same content?
The clearer the answers to these questions, the easier it is for Google to understand the site.
To sum up
We can roughly think of the path Google takes to bring a page into search results like this:
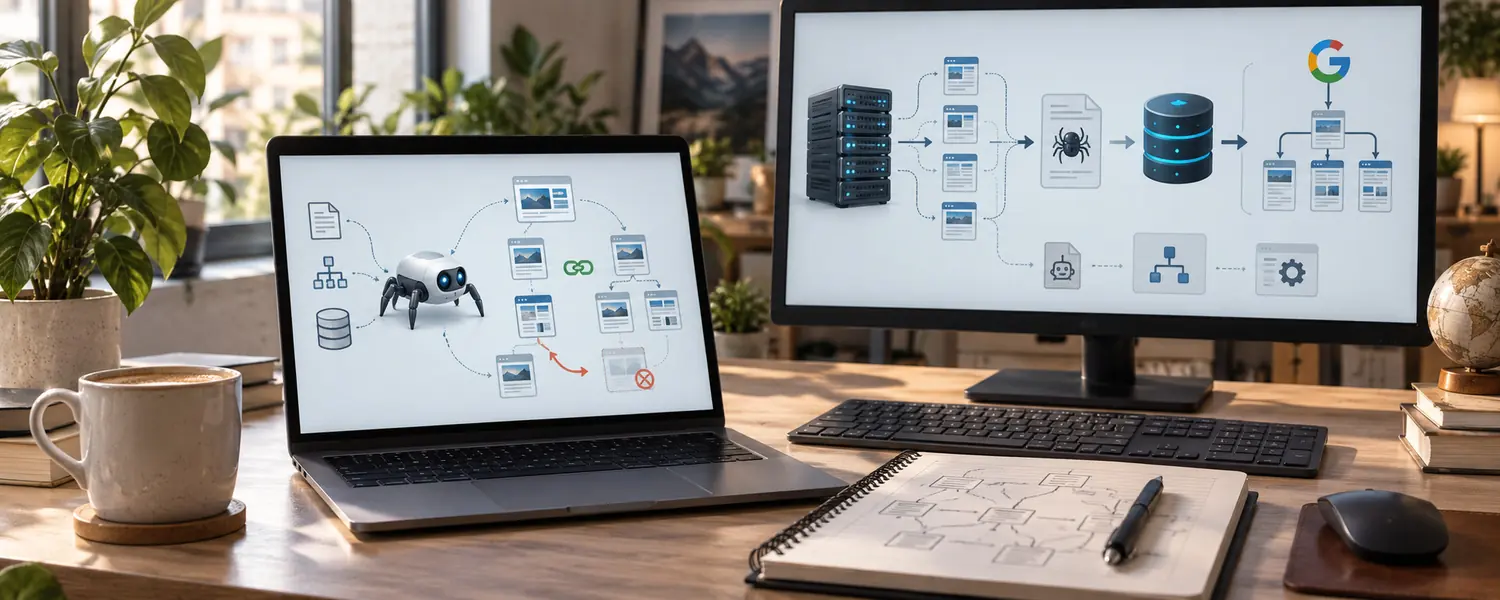
Discover the URL → Check whether crawling is allowed → Request the page → Get the HTTP response → Read the content → Evaluate similar URLs → Choose the canonical → Make the indexing decision → Recrawl over time
robots.txt, sitemap.xml, 301, 302, 404, canonical, noindex, pagination and crawl budget actually manage different points in this process.
More important than memorizing each of them is understanding which tool solves which problem.
Problems start when we try to manage the index with robots.txt, remove pages with a canonical or send every unrelated 404 to the homepage with a 301.
In technical SEO, the good solution usually isn’t complicated.
Clear the path in front of Googlebot and give it signals that don’t contradict each other.
Previous: Chapter 22: How to Plan Before Writing: The Content Brief · Contents · Next: Chapter 24: Why Is the Site Slow?
This chapter was first published in Turkish on X (September 25, 2026).